Exploring OpenDal: A Unified Approach to Object Store unstructured data

If you’ve ever worked with Delta tables, for example using delta_rs, you know that writing to one is as simple as passing the URL and credentials. It doesn’t matter whether the URL points to OneLake, S3, Google Cloud, or any other major object store — the process works seamlessly. The same applies whether you’re writing data using Spark or even working with Iceberg tables.

However, things get complicated when you try to list a bucket or copy a file. That’s when the chaos sets in. There is no standard method for these tasks, and every vendor has its own library. For instance, if you have a piece of code that works with S3, and you want to replicate it in Azure, you’ll need to rewrite it from scratch.

This is where OpenDal comes in. OpenDal is an open-source library written in Rust (with Python bindings) that aims to simplify this problem. It provides a unified library to abstract all object store primitives, offering the same API for file management across multiple platforms (or “unstructured data” if you want to sound smart). While the library has broader capabilities, I’ll focus on this particular aspect for now.

I tested OpenDal with Azure ADLS Gen2, OneLake, and Cloudflare R2. To do so, I created a small Python notebook (with the help of ChatGPT) that syncs any local folder to remote storage. It works both ways: if you add a file to the remote storage, it gets replicated locally as well.

Currently, there’s a limitation: OpenDal doesn’t work with OneLake yet, as it doesn’t support OAuth tokens, and SAS tokens have a limited functionality ( it is by design, you can’t list a container for example from OneLake)

You can download the notebook here

Here’s an example of how it works:

you need just to define your object store and the rest is the same, list, create folder, copy, write etc all the same !!! this is really a very good job

you can see the presentation but it is too technical to my taste 🙂 https://www.youtube.com/watch?v=eVMIzY1K5iQ

Local folder :

Cloudflare R2:

TPC-DS 100GB with Only 2 Cores and 16 GB of RAM

As the year comes to a close, I decided to explore a fun yet somewhat impractical challenge: Can DuckDB run the TPC-DS benchmark using just 2 cores and 16 GB of RAM? The answer is yes, but with a caveat—it’s slow. Despite the limitations, it works!

Notice; I am using lakehouse mounted storage, for a background on the different access mode, you can read the previous blog

Data Generation Challenges

Initially, I encountered an out-of-memory error while generating the dataset. Upgrading to the development release of DuckDB resolved this issue. However, the development release currently lacks support for reading Delta tables, as Delta functionality is provided as an extension available only in the stable release.

Here are some workarounds:

  1. Increase the available RAM.
  2. Use the development release to generate the data, then switch back to version 1.1.3 for querying.
  3. Wait for the upcoming version 1.2, which should resolve this limitation.

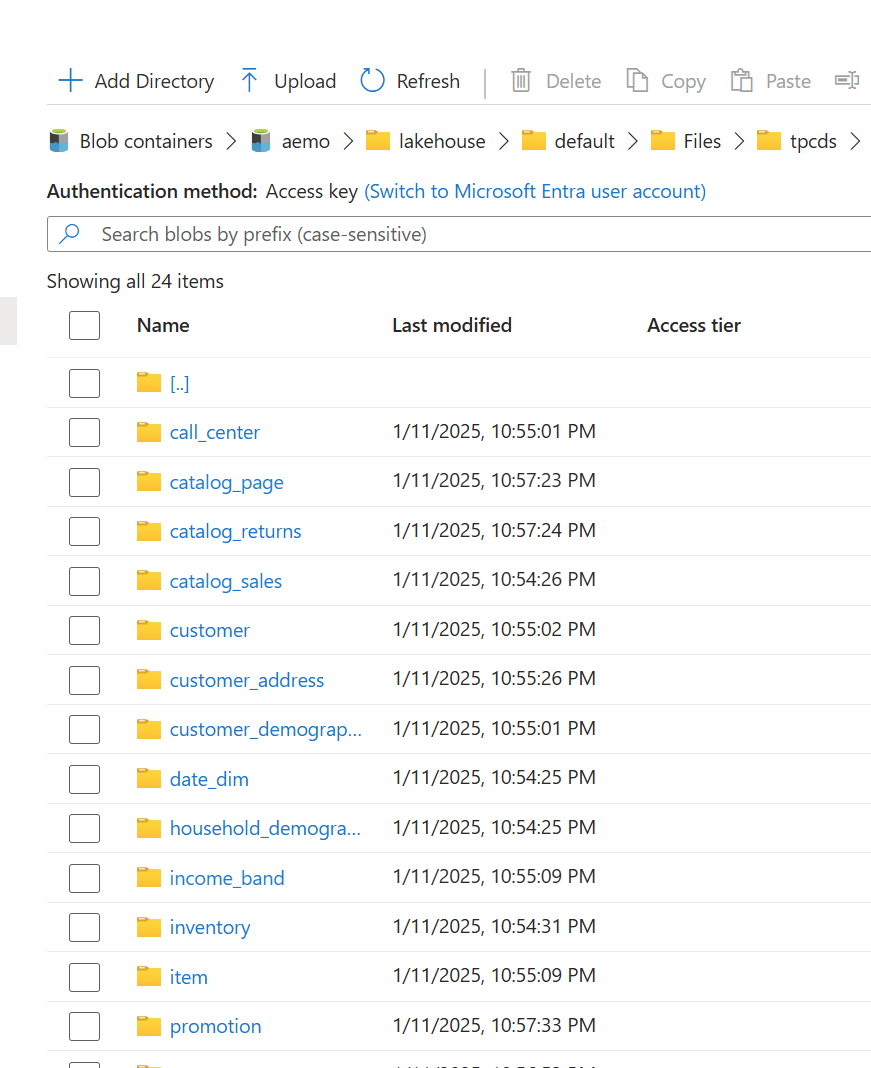
The data is stored as Delta tables in OneLake, it was exported as a parquet files by duckdb and converted to delta table using delta_rs (the conversion was very quick as it is a metadata only operation)

Query Performance

Running all 99 TPC-DS queries worked without errors, albeit very slowly( again using only 2 cores ).

I also experimented with different configurations:

4, 8, and 16 cores: Predictably, performance improved as more cores were utilized.

For comparison, I ran the same test on my laptop, which has 8 cores and reads my from local SSD storage, The Data was generated using the same notebook.

Results

Python notebook compute consumption is straightforward, 2 cores = 1 CUs, the cheapest option is the one that consume less capacity units, assuming speed of execution is not a priority.

  • Cheapest configuration: 8 cores offered a good balance between cost and performance.
  • Fastest configuration: 16 cores delivered the best performance.

Interestingly, the performance of a Fabric notebook with 8 cores reading from OneLake was comparable to my laptop with 8 cores and an SSD. This suggests that OneLake’s throughput is competitive with local SSDs.

Honestly, It’s About the Experience

At the end of the day, it’s not just about the numbers. There’s a certain joy in using a Python notebook—it just feels right. DuckDB paired with Python creates an intuitive, seamless experience that makes analytical work enjoyable. It’s simply a very good product.

Conclusion

While this experiment may not have practical applications, it highlights DuckDB’s robustness and adaptability. Running TPC-DS with such limited resources showcases its potential for lightweight analytical workloads.

You can download the notebook for this experiment here: