Querying a Onelake Table with RLS and CLS Using DuckDB’s MSSQL Extension

Onelake supports Row Level Security and Column Level Security. These protections work when you use trusted engines such as Power BI or Spark running inside Microsoft Fabric. In those environments, the compute engine operates within a controlled boundary, so security rules can be enforced properly.

However, if you try to access the storage directly from a Python notebook or a local engine running on your laptop, including open source Spark, direct access is blocked. Otherwise, Row Level Security and Column Level Security would be meaningless. Security only works when the engine itself is trusted and governed.

This blog show a workaround by laveraging SQL Endpoint, These policies are enforced at the SQL endpoint, meaning any external tool that connects through it — including DuckDB — automatically respects them.

Let’s walk through a quick example.

The Data

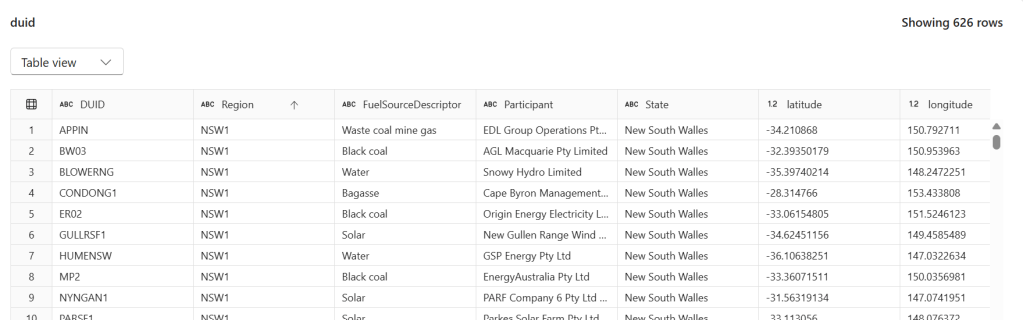
We have a power.duid table containing 626 rows of Australian power generation facilities. Columns include DUID, Region, FuelSourceDescriptor, Participant, State, latitude, and longitude.
Configuring Row-Level Security

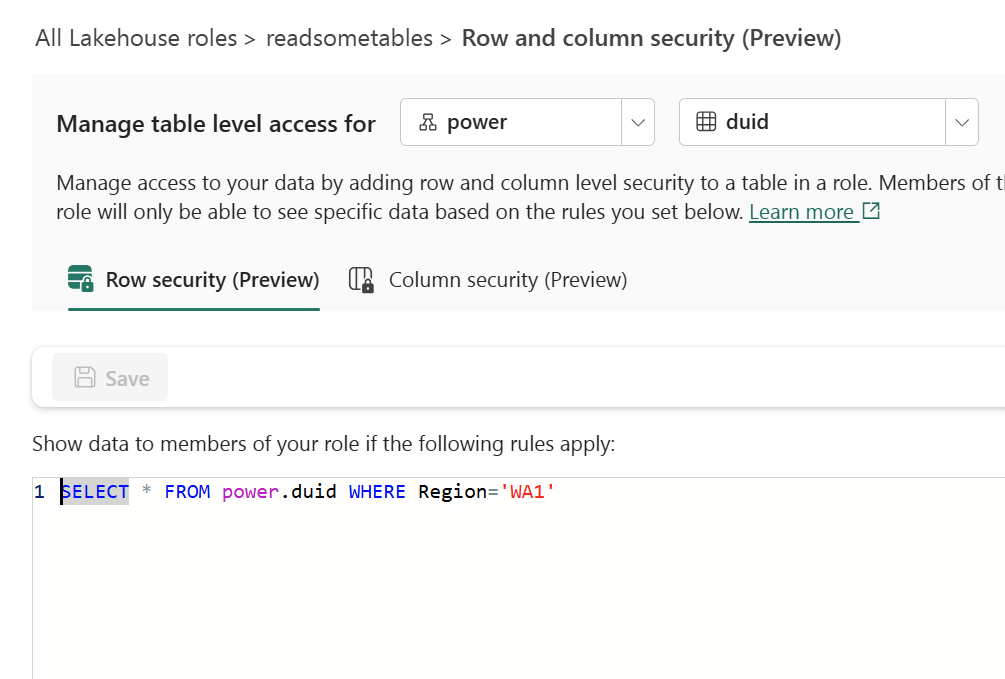
In the Lakehouse role readsometables, we add an RLS rule that restricts visibility to a single region:

SELECT * FROM power.duid WHERE Region='WA1'

Members of this role will only see rows where Region = 'WA1'.
Configuring Column-Level Security

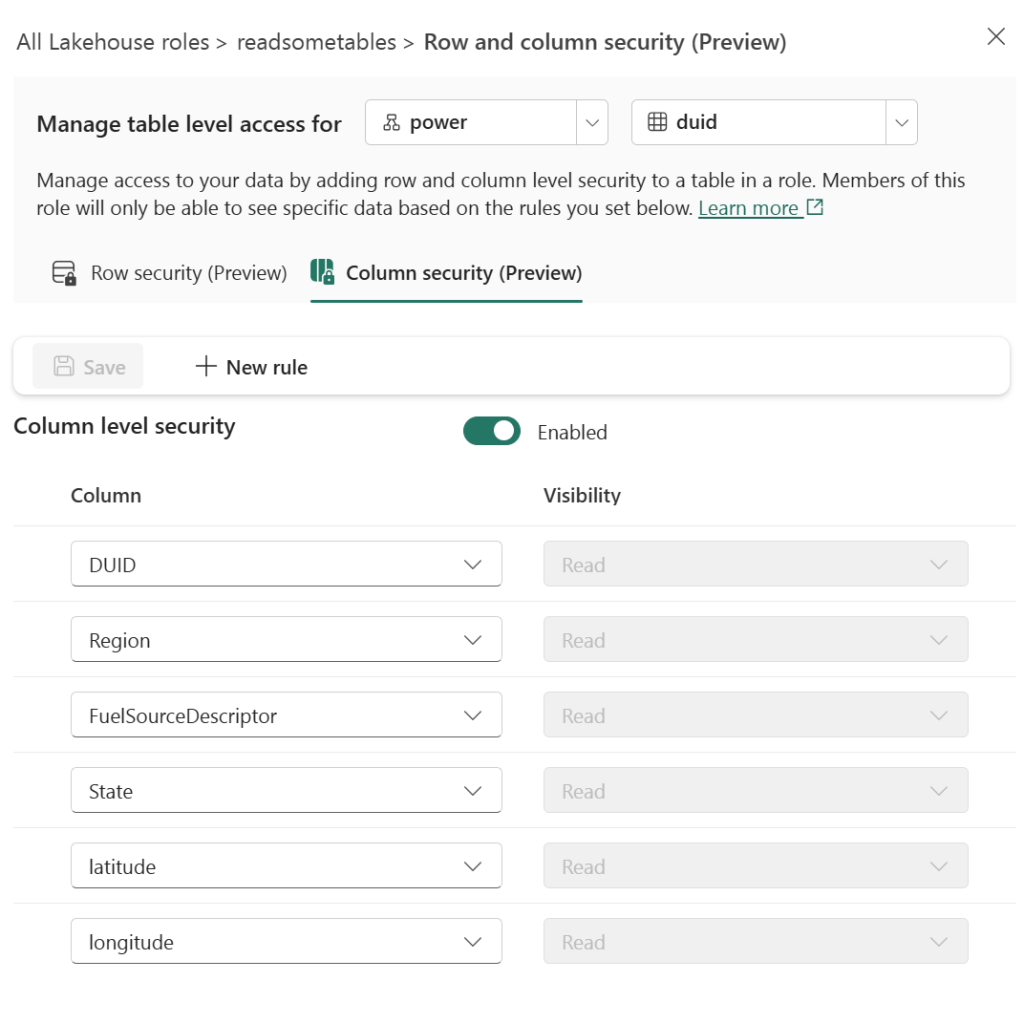
On the same role, we enable CLS and grant Read visibility only to specific columns: DUID, Region, FuelSourceDescriptor, State, latitude, and longitude. The Participant column is excluded.
Querying with DuckDB’s MSSQL Extension

From any Python environment, we can connect to the SQL endpoint using DuckDB’s community MSSQL extension and Azure authentication:

import duckdb
from azure.identity import DefaultAzureCredential

conn = duckdb.connect()
token = DefaultAzureCredential().get_token("https://database.windows.net/.default").token

conn.sql(f"""
    ATTACH IF NOT EXISTS
    'Server=<your-sql-endpoint>;Database=data'
    AS data (TYPE mssql, ACCESS_TOKEN '{token}')
""")

if you are running it inside Fabric notebook, first you need to updgrade duckdb,

!pip install duckdb --upgrade
import sys
sys.exit(0)

the run this code

import duckdb
conn = duckdb.connect()
token = notebookutils.credentials.getToken('sql')
conn.sql(f"""
install mssql from community ;
ATTACH if not exists
'Server=SQL_endpoint;Database=data'
AS data (TYPE mssql, ACCESS_TOKEN '{token}')
""")


Now when we query, RLS and CLS are enforced server-side:

conn.sql("SELECT DISTINCT(Region) FROM data.power.duid").show()
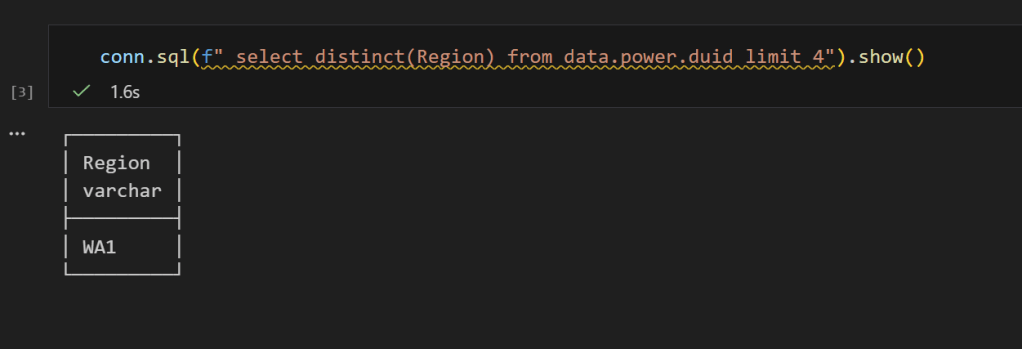
Only WA1 — the RLS filter is working. And if we select all columns:

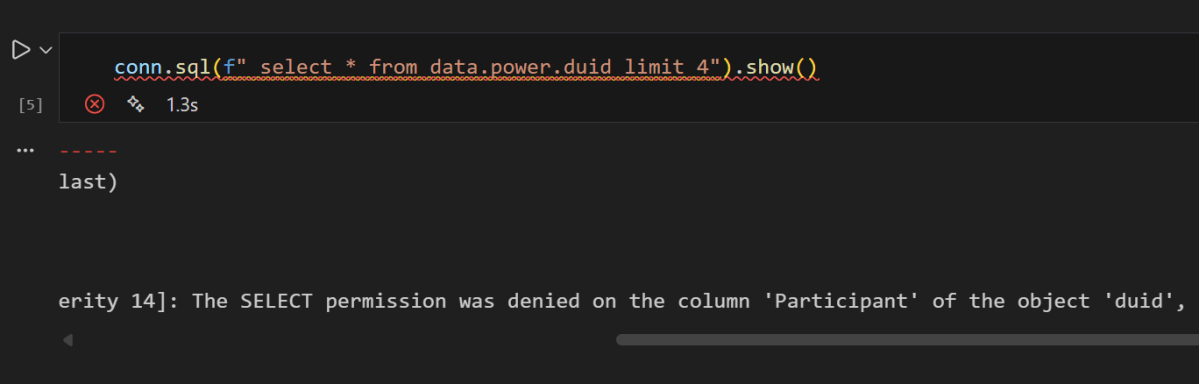
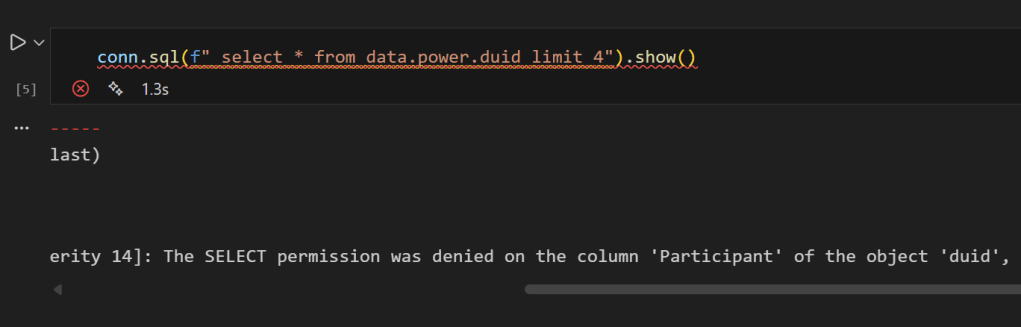
conn.sql("SELECT * FROM data.power.duid LIMIT 4").show()

you get an error, that you can not select Participant
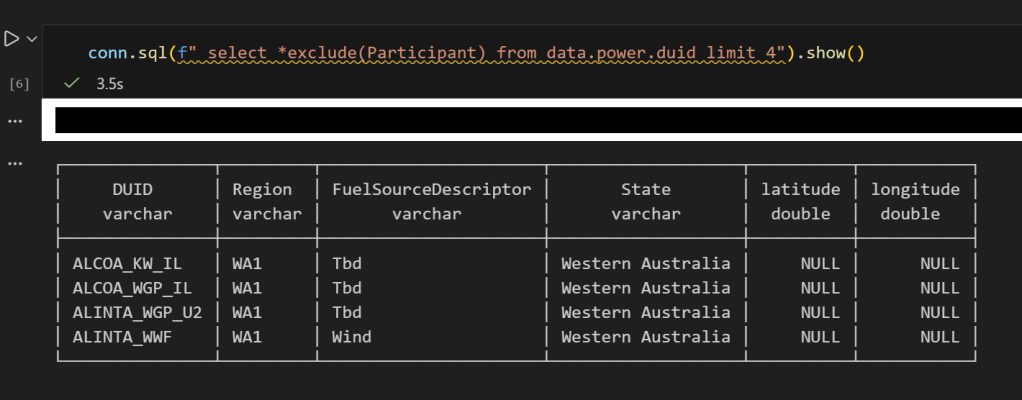
No Participant column — CLS is doing its job, now if you remove it , everything works fine
Query Onelake Iceberg REST catalog using Duckdb SQL

it is a quick post on how to query Onelake Iceberg REST Catalog using pure SQL with DuckDB, and yes you need a service principal that has access to the lakehouse

CREATE or replace PERSISTENT secret onelake_identity_iceberg (
    TYPE ICEBERG,
    CLIENT_ID 'xxxxxxxxxxxxxx',
    CLIENT_SECRET 'yyyyyyyyyyyyyyyyyyy' ,
    OAUTH2_SCOPE   'https://storage.azure.com/.default' ,
    OAUTH2_SERVER_URI 'https://login.microsoftonline.com/TENANT_ID /oauth2/v2.0/token' ,
    ENDPOINT 'https://onelake.table.fabric.microsoft.com/iceberg'
);
CREATE or replace PERSISTENT secret azure_spn (
    TYPE azure,
    PROVIDER service_principal,
    TENANT_ID 'ccccccc',
    CLIENT_ID 'iiiiiiiiiiiiii',
    CLIENT_SECRET 'xbndlfrewi' ,
    ACCOUNT_NAME 'onelake'
);

it works reasonably well assuming your region is not far from your laptop, or even better , if you run it inside Fabric then there is no network shenanigans, I recorded a video showing my experience

Why read operations do not always need full consistency checks

I hope DuckDB eventually adds an option that allows turning off table state checks for purely read scenarios. The current behaviour is correct because you always need the latest state when writing in order to guarantee consistency. However, for read queries it feels unnecessary and hurts the overall user experience. PowerBI solved this problem very well with its concept of framing, and something similar in DuckDB would make a big difference, notice duckdb delta reader already support pin version.

First Look at OneLake Diagnostics

While preparing for a presentation about the FabCon announcement, one item was about OneLake Diagnostics. all ll I knew was that it had something to do with security and logs. As a Power BI user, that’s not exactly the kind of topic that gets me excited, but I needed to know at least the basic, so I can answer questions if someone ask 🙂

Luckily, we have a tradition at work , whenever something security-related comes up, we just ping Amnjeet 🙂

He showed me how it works , and I have to say, I loved it. It’s refreshingly simple.

You can download the notebook here:


You just select a folder in your Lakehouse and turn it on.

That’s it , the system automatically starts generating JSON files, neatly organized using Hive-style partitions, By default, user identity and IP tracking are turned off unless an admin explicitly enables them. You can find more details about the schema and setup here.


What the Logs Look Like

Currently, the logs are aggregated at the hourly level, but the folder structure also includes a partition for minutes (even though they’re all grouped at 00 right now).

Parsing the JSON Logs

Once the logs were available, I wanted to do some quick analysis , not necessarily about security, just exploring what’s inside.

There are probably half a dozen ways to do this in Fabric ; Shortcut Transform, RTI, Dataflow Gen2, DWH, Spark, and probably some AI tools too, Honestly, that’s a good problem to have.

But since I like Python notebooks and the data is relatively small, I went with DuckDB (as usual), but Instead of using plain DuckDB and delta_rs to store the results, I used my little helper library, duckrun, to make things simpler ( Self Promotion alert).

Then I asked Copilot to generate a bit of code for registering existing functions to look up the workspace name and lakehouse name from their GUIDs in DuckDB, using SQL to call python is cool 🙂


The data is stored incrementally, using the file path as a key , so you end up with something like this:

import duckrun

con = duckrun.connect('bigdata/tpch.lakehouse/dbo')

onelake_logs_path = (
    'abfss://bigdata@onelake.dfs.fabric.microsoft.com/'
    'tpch.Lakehouse/Files/DiagnosticLogs/OneLake/Workspaces/*/'
    'y=*/m=*/d=*/h=*/m=*/*.json'
)

Then I added only the new logs with this SQL script:

try:
    con.sql(f"""  
        CREATE VIEW IF NOT EXISTS logs(file) AS SELECT 'dummy';
        SET VARIABLE list_of_files =
        (
            WITH new_files AS (
                SELECT file
                FROM glob('{onelake_logs_path}')
                WHERE file NOT IN (SELECT DISTINCT file FROM logs)
                ORDER BY file
            )
            SELECT list(file) FROM new_files
        );
        SELECT * EXCLUDE(data), data.*, filename AS file  
        FROM read_json_auto(
            GETVARIABLE('list_of_files'),
            hive_partitioning = true,
            union_by_name = 1,
            FILENAME = 1
        )
    """).write.mode("append").option("mergeSchema", "true").saveAsTable('logs')
except Exception as e:
    print(f"An error occurred: {e}")

1- Using glob() to collect file names means you don’t open any files unnecessarily , a small but nice performance win.

2- DuckDB expand the struct using this expression data.*

3- union_by_name = 1 in case the json has different schemas

4- option(“mergeSchema”, “true”) for schema evolution in Delta table


Exploring the Data

Once the logs are in a Delta table, you can query them like any denormalize table.

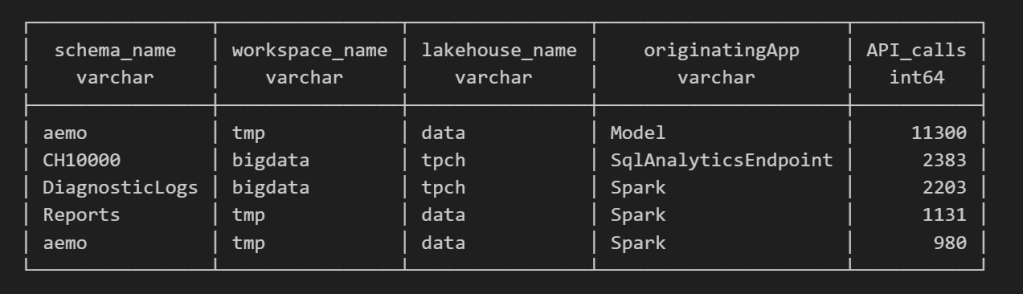
For example, here’s a simple query showing API calls per engine:

Note : using AI to get working regex is maybe the best thing ever 🙂

SELECT
    regexp_extract(resource, '([^&/]+)/([^&/]+)/(Tables|Files)(?:/([^&/]+))?(?:/([^&/]+))?', 4) AS schema_name,
    get_workspace_name(workspaceid) AS workspace_name,
    get_lakehouse_name(workspaceid, itemId) AS lakehouse_name,
    originatingApp,
    COUNT(*) AS API_calls
FROM logs
GROUP BY ALL
ORDER BY API_calls DESC
LIMIT 5;

Fun fact: OneLake tags Python notebook as Spark.
Also, I didn’t realize Lineage calls OneLake too!

as I have already register Python functions as UDFs, which is how I pulled in the workspace and lakehouse names in the query above.


Takeaway

This was just a bit of tinkering, but I’m really impressed with how easy OneLake Diagnostics is to set up and use.

I still remember the horrors of trying to connect Dataflow Gen1 to Azure Storage ,that was genuinely painful (and I never even got access from IT anyway).

It’s great to see how Microsoft Fabric is simplifying these scenarios. Not everything can always be easy, but making the first steps easy really gives the feature a very good impression.

Does a Single-Node Python Notebook Scale?

I was giving a presentation about Microsoft Fabric Python notebooks and someone asked if they scale. The short answer is yes. You can download the notebook and try it for yourself. For the long answer, keep reading.

The dataset I used contains the last seven years of Australian electricity market data. Although it’s public, the government agency only keeps archives for two months. I had saved the data during a previous job and kept it around as a hobby. It’s a great real-world workload with realistic data distribution. The CSV files are messy. Technically, they’re more like reports, with different sections stacked on top of each other and varying numbers of columns. That’s often what you encounter in real projects, not the neat, well-structured datasets you see in demos.

For example, being able to read a CSV file with a variable number of columns is a critical feature. Yet this rarely gets mentioned in synthetic benchmarks.

To create a clean environment for testing, I copied the data from one Lakehouse in onelake to a brand-new workspace. I could have used a shortcut, but I wanted to start from scratch. The binary copy took just 2 minutes, with no transformations, which gives a throughput of 1.4 GB per second. That’s pretty good for a 150 GB uncompressed dataset.

The default configuration for Fabric Python notebooks includes 2 cores and 16 GB of RAM. That’s roughly the same size as Google Colab. But you can easily increase the number of cores to 4, 8, 16, 32, or even 64. At 64 cores, you get nearly half a terabyte of RAM. That’s a serious machine.

The job itself is simple. Ingest and process the data using several Python engines, then save the result as a Delta table. The raw data has around one billion records, and you end up extracting 311 million. If your engine cannot push down filters to the CSV level, you’re going to have a hard time. The trick here is not to be fast, but to avoid doing unnecessary work.

I used the following engines: DuckDB, Daft, Polars, CHDB (basically ClickHouse for Python), DataFusion, PyArrow, and Pandas. Technically, Pandas is not ideal here because you can’t pass a list of files without using a loop. But I had used it for nearly seven years, so I kept it for sentimental reasons.

I’m fairly confident using all of these engines except PyArrow and DataFusion. Their syntax is very intimidating, and I probably missed some configuration settings. I couldn’t get them to use more than a single thread, so CPU utilization stayed very low.

Results

  • Polars support streaming writes, but doesn’t allow exporting a record batch. This means the Delta writer has to load all data into memory. It works fine with 32 cores and 256 GB of RAM, but you’ll run into out-of-memory issues with 16 cores and below.
  • Chdb 3.5 added a user friendly way to export arrow record batch, it is the first release so still some bugs, for example got an error with 2 cores, I am sure it will get fixed soon
  • Daft is the only engine that supports native writing to Delta. It uses the Deltalake package only to commit the transaction log. The actual Parquet write is handled by the engine itself.
  • DuckDB preserves the sort order of the input files. it is trick to appeal to Pandas users who care about index ordering. For best performance though, you should turn this off. (Honestly, I think it should be off by default)
  • DuckDB exports Arrow tables by default. You need to explicitly use record_batch(). I’ve lost count of how many out-of-memory issues I’ve solved just by changing the export format.
  • Overall, DuckDB delivered the best performance, especially considering it’s not even writing Parquet files directly. It simply streams Arrow data to the writer.

When I first ran the test with DuckDB and saw it finish in under 4 minutes, I thought I made a mistake. It wasn’t until CHDB finished in under 5 minutes that I realized these engines are seriously impressive.

We’re talking about 625 MB per second for processing and ingestion on a single node.

Another key observation: using DuckDB and Daft, even with just 16 GB of RAM, the data was processed correctly. It took about an hour, but it worked without errors, that’s 10 X the size of the RAM

To verify correctness, I simply checked the total sum of a column and the number of records. Everything checked out.

Choosing the Right Size

Now that I know these notebooks work, choosing the right size becomes more nuanced. Surprisingly, the cheapest configuration in term of capacity usage was the 2 cores 🙂

In practice though, using more compute makes sense. A single node has no concept of fault tolerance. If something goes wrong, you need to restart the entire job. Personally, I’m not a fan of long-running jobs. Too many things can go wrong. I used 2 cores just to make a point. That said, using 64 cores doesn’t make much sense either. You’re doubling your compute cost to save 30 seconds.

One more thing: while Daft scales down very well, it doesn’t seem to scale up as efficiently as I had hoped. Ideally, you want a flat performance curve. The total amount of work is fixed, so adding more cores should just reduce execution time. I know the reality is more complex. It’s not easy to keep all processors busy at higher scales.

What This Means

As you may have guessed, I’m a big fan of single-node setups and DuckDB. But I don’t want just one engine to dominate every benchmark or deliver results that no other engine in its class can match. That’s why I was genuinely excited by Daft’s performance. I’m also looking forward to seeing Polars and CHDB add Arrow streaming support.

To be honest, I look at the world from a storage perspective. More competition between engines is a good thing. All of these tools are open source under the MIT license. Most of them can write to Delta in one form or another. and as a user you can choose any engine you want, I think that’s a fantastic thing to have.

So yes, Python notebooks do scale. The experience is far from being perfect, and there’s still room for improvement. But scalability is not something you should worry about, unless of course you are really doing real big data, then you go distributed 🙂 DWH and Spark are robust options in Fabric.

Edit : tested with chdb 3.5 which has support for arrow streaming