The file section of Fabric Lakehouse is very interesting as although it is a blob storage, somehow behaves more or less like a real filesystem, we leverage that to save all Delta Tables in one DuckDB file
Limitation
DuckDB storage format is experimental at this stage and doesn’t offer backward compatibility yet, everytime they upgrade a major version, you have to export the file to parquet and import it back.
I am using Python Deltatlake package to read the Delta table, currently it supports only Delta reader version 1, which Microsoft uses, but this may change in a future update of Fabric.
The data will be saved for the current version of the table, old data not removed by vacuum will be ignored.
A note about concurrency
You can have multiple readers using the file at the same time (Using read_only=True), but multiple writers is not a supported scenario nor 1 Writer and multiple reader, use at your own risk 🙂 Having said that, in the case of 1 writer and multiple reader the worst case scenario is reading inconsistent data 🙂
TL;DR : using Fabric Python Notebook to Sort and Save Parquet files up to 100 GB shows that DuckDB is very competitive compared to Spark even when using Only half the resources available in a compute pool.
Introduction :
In Fabric the minimum Spark compute that you can provision is 2 nodes, 1 Driver and 1 Executor, my understanding, and I am not an expert by any means is : Driver Plan the Work and Executor do the actual Works, but if you run any no Spark code, it will run in the driver, basically DuckDB use only the driver, the executor is just sitting there and you pay for it.
The experiment is basically : generate the Table Lineitem from the TPCH dataset as a folder of parquet files and sort it on a date field then save it. Pre-sorting the data on a field used for filtering is a very well known technique.
Create a Workspace
When doing POC, it is always better to start in a new workspace, at the end you can delete it and it will remove all the artifacts inside it. Use any name you want.
Create a Lakehouse
Click New then Lakehouse, choose any name
You will get an empty lakehouse (it is a just a storage bucket with two folders, Files and Table)
Load the Python Code
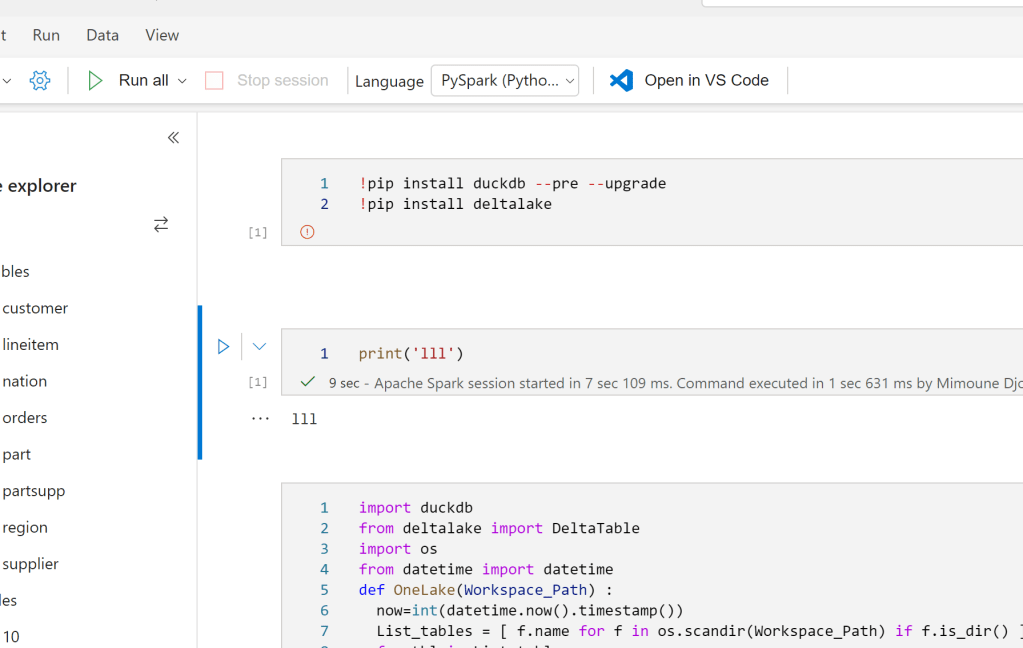
The Notebook is straightforward, Install DuckDB , create the data files if they don’t exist already, sort and save in a delta table using both DuckDB and Spark
Define Spark Pool Size
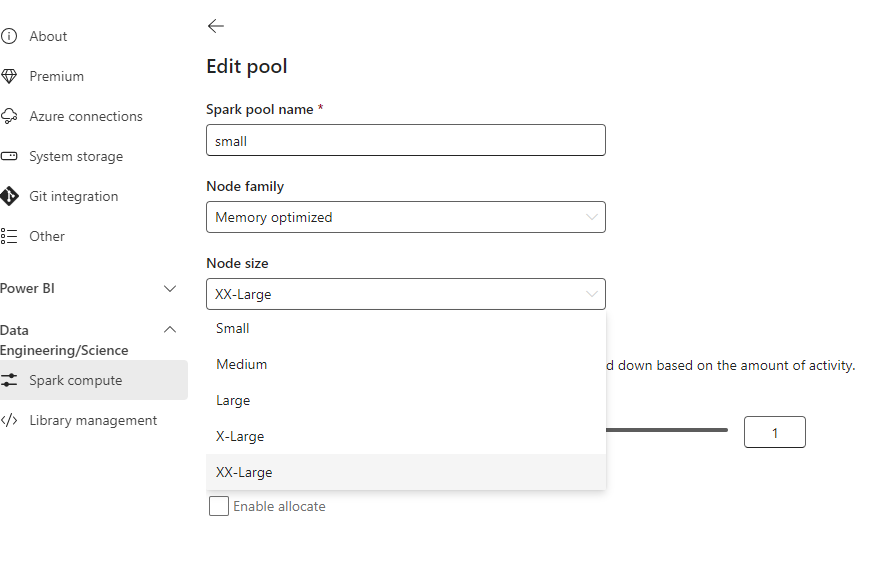
By default the notebook came with a starter pool that are warm and ready to be used, the startup is in my experience is always less than 10 second, but it is a managed service and I can’t control the number of nodes, instead we will use custom pool where you can choose the size of the compute and the number of nodes in our case 1 driver and 1 executor, the startup is not bad at all, it is consistently less than 3 minute.
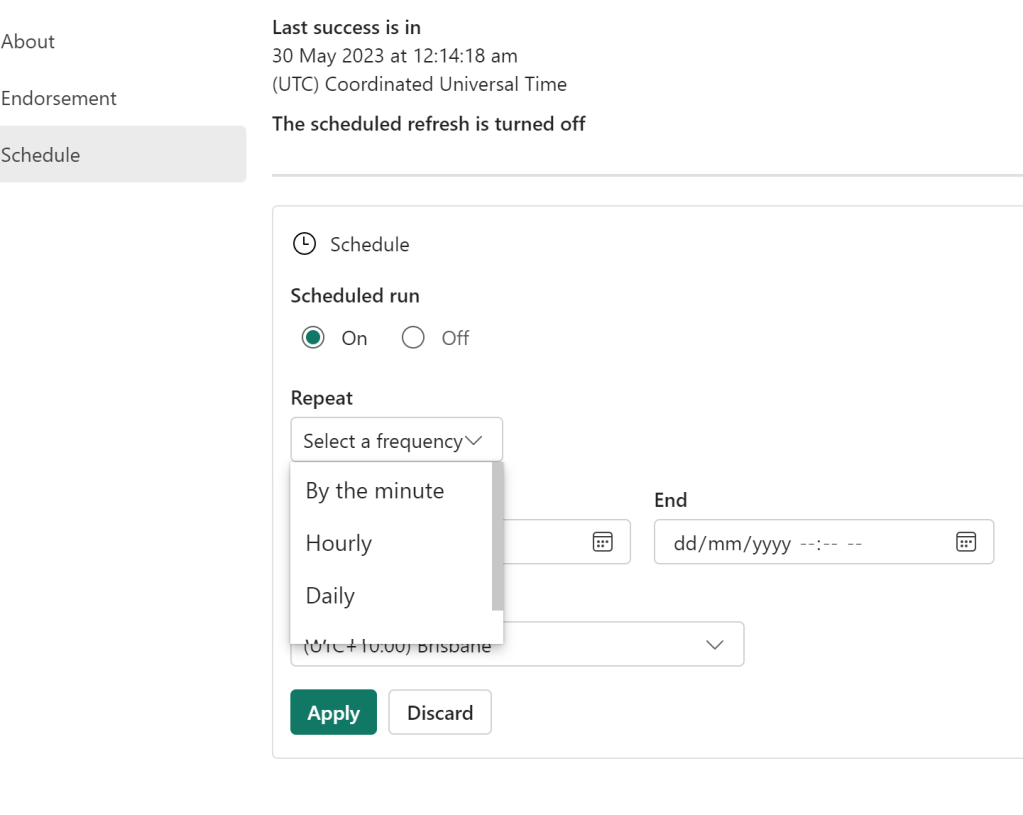
Schedule the Notebook
I don’t not know, how to pass a parameter to change the initial value in the pipeline, so I run it using a random number generator`, I am sure there is a better way, but anyway, it does works, and every insert the results
The Results
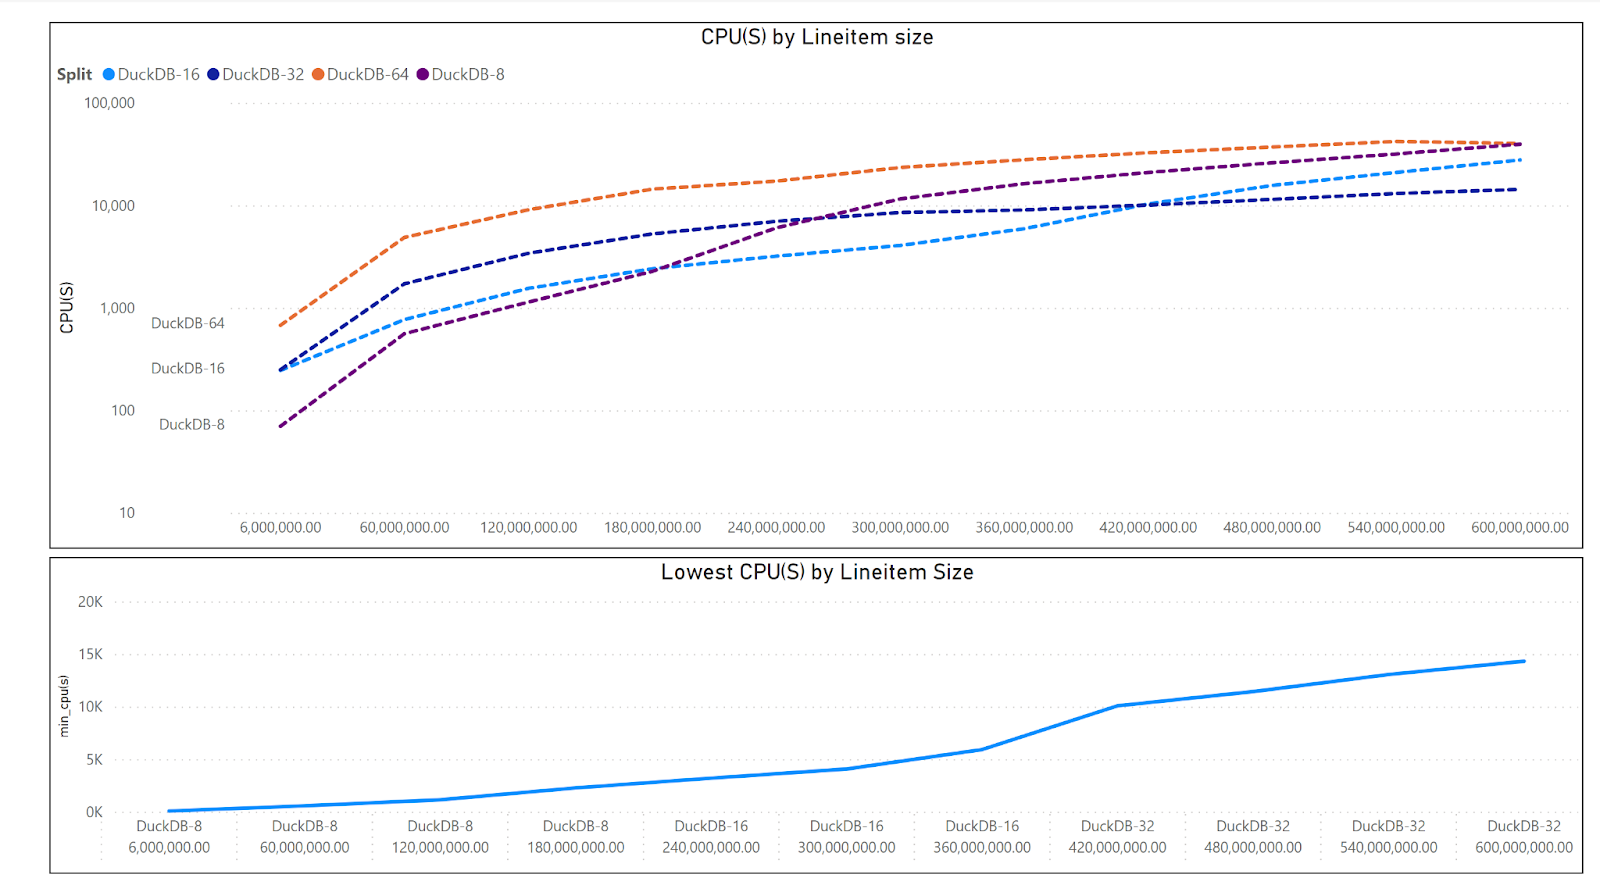
The Charts show the resource usage by data size, CPU(s) = Duration * Number of cores * 2.
Up to 300 Million rows, DuckDB is more efficient even when it is using only half the resources.
To make it clearer , I build another chart that show the Engine combination with less resource utilization by Lintem size
From 360 Million rows, Spark became more economical ( with the caveat that DuckDB is just using half the resources) or maybe DuckDB is not using the whole 32 cores ?
Let’s filter only DuckDB
DuckDB using 64 cores is not very efficient for the size of this Data.
Partying Thoughts
Adding more resources to a problem does not make it necessarily an optimal solution, you get faster duration but it costs way more.
DuckDB Performance even using half the compute is very intriguing !!!
Fabric Custom pools are a very fine solution, waiting around 2 minutes is worth it.
I am no Spark expert, but it will be handy to be able to configure at runtime a smaller Executor compute, in that case, DuckDB will be cheaper option for all sizes up to 100 GB and maybe more.
Edit :4-sep-2023 : Fabric added supported for single node with started pool, that literally changed the product, I am keeping the blog for “historical” reason 🙂
TL:DR; Fabric redefined the meaning of self service Python experience, but I think it is recommended to turn off Serverless compute till we have a knob to configure the maximum number of nodes, Spark for small workload is not very impressive and there are better alternatives. In TPCH-SF100 DuckDB was nearly 10 times cheaper.
Fabric provide a serverless Python experience, you don’t need to provision anything, you write code and click run
I have to admit, it stills feel weird to open PowerBI and see Notebook in the workspace, maybe this will be the biggest boost to Python in non tech companies,
You can actually Schedule a Notebook without writing any code, yep no cron job.
Local Path
Somehow you read and write to OneLake which is an ADLS Gen2 using just local path, it was so seamless that I genuinely thought I was writing to a local filesystem, that’s really great works, it did work with Pandas , Spark obviously and DuckDB, there are bugs though, Delta Lake writer (Python not Spark) generate an error
Default Runtime
Microsoft maintains a massive pool of warm Spark VM, waiting to be called by users, it is pretty much a sub 10 second in my experience
You can build your own cluster but it will not be serverless, and you have to wait for up to 5 minutes. To be honest, I did try it and got an error, it seems the product team is aware of it and will push a fix soon.
Resource management in Spark is weird
DWH are really good at working with multiple users concurrently, you write a Query you send it to the DB you get results back, a DB can accept multiple Queries concurrently and can even put your Query under heavy traffic in a queue. And can return results instantaneously if the queries are the same. As far as I can tell, at least in Fabric, everytime you run a notebook, it will spin up a new Spark compute the sessions are not shared ( it is planned though) and you can’t configure how many vm Spark decided to use, in theory it is handled by the system, I am afraid it is a very problematic decision.
Take for example BigQuery scan mode, it is totally serverless and can use a massive amount of resources, but that’s not an issue for the user, you pay by data scanned, the resource is BigQuery Problem. For Fabric Spark serverless you pay by compute used and there is no way to assign a maximum limit, (it seems it is coming soon,but I believe only what I see) honestly that’s a very strange decision by Fabric product team.
In the trial capacity we have 1 Driver and up to 10 executors, and the clusters are not shared, you can easily consume all your capacity if you have some users that just write some silly code in Python, this is scary.
Testing resources Allocation in Spark Serverless
Spark Serverless assume the Engine will just allocate what’s required, so technically , for a smaller workload it will use only 1 node ( is it 1 driver or 1 driver + 1 executor I don’t know)
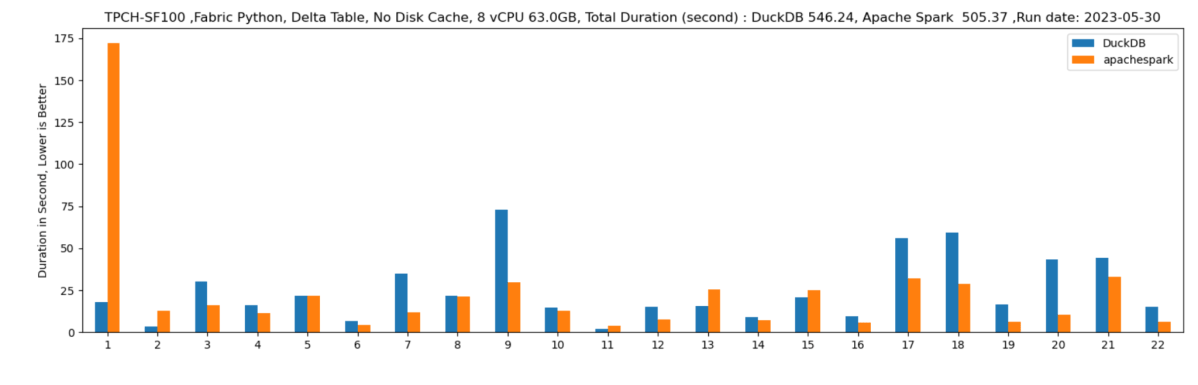
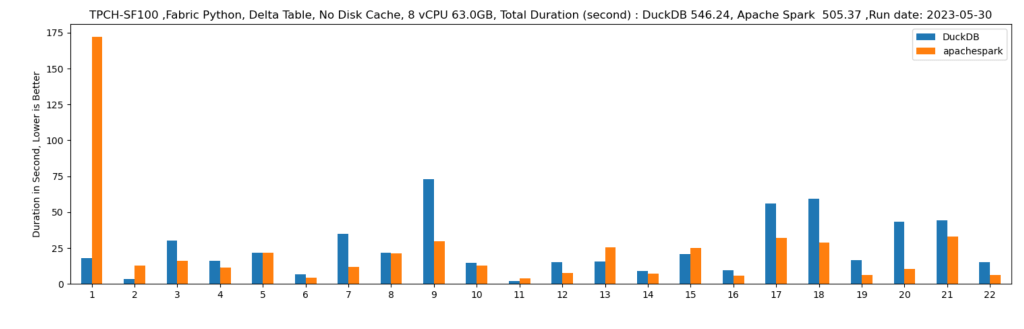
Let’s run some benchmarks and see how it behaves in real life. I generated a TPCH dataset with a scale factor of 100, it is more a less a 100 GB of data not compressed, it is relatively small data and should work just fine in 1 node (8 CPU and 63 GB of RAM). I used DuckDb as a baseline,The code for generating the data and running the benchmarks is shared here
DuckDB : 546 second
Spark : 505 second.
DuckDB is using 1 node, Spark is using 11 Nodes ( 1 Driver and 10 executors)
Parting Thoughts
An option to configure the numbers of nodes is a must have before billing start in the first of July
Why Spark, I am afraid Microsoft is repeating the same mistake of Dedicated Pool, a system designed for very big data but does not work well with sub 1 TB workload, even Databricks the inventor of Spark recognized that and Built the Photon Engine which is in C++, customers will end up paying for JVM bottleneck
Microsoft has already a great experience with Azure ML that uses a single node. Why is it not available now ? it is 2023, There are many options with ultra fast single node Query Engine like Polars, DuckDB, Data fusion etc.
My intuition is Synapse DWH Engine will be a cheaper option here when the offering becomes more mature.
I stand by everything I wrote here, but not all Engines are equal in Fabric.
in a previous blog, I did benchmark some database using TPCH-SF100, one of the main complaint was that the data was originally from snowflake although I did rewrite the parquet files using DuckDB, it did not feel right as Snowflake performance using the lowest tier was exceptionally good, in this blog, I am using Data generated independently, and yes Snowflake is very fast.
Reproducibility
Since that blog, DuckDB released a new update where you can generate any TPCH data using low resource computer (like my laptop), I thought it is a good opportunity to validate the previous results, this time though, I published the full pipeline so, it can be reproduced independently.
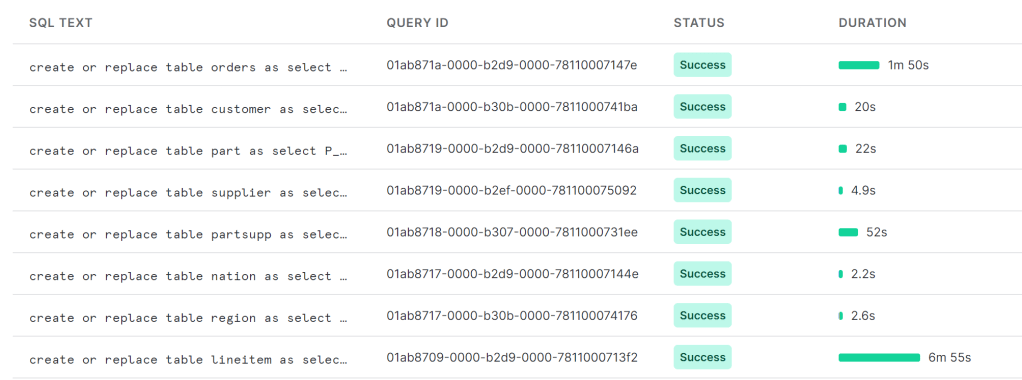
Import the data from Azure Storage to Snowflake native table using create table as select from external table, the import took around 10 minutes ( that was rather slow to be honest), the data is imported as it is, no sorting, and no table distribution shenanigans.
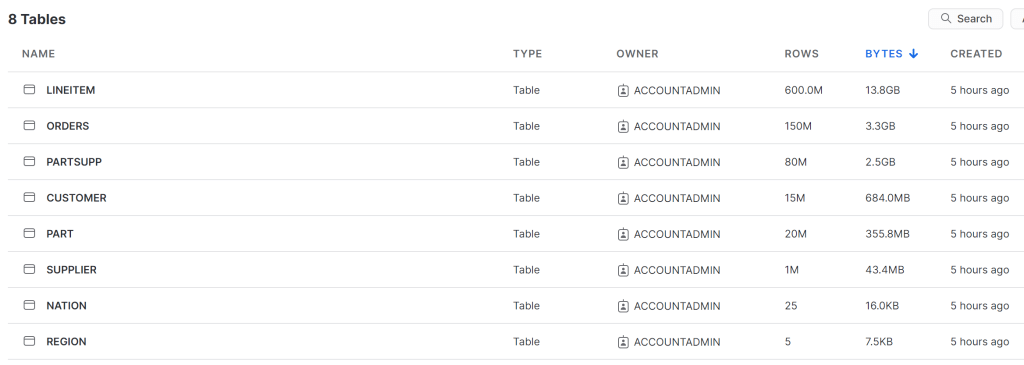
I did noticed Snowflake has a better compression ratio than Parquet, for example the table “lineitem” size in Parquet is 25 GB, in Snowflake file format is 13.8 GB
Run TPCH benchmarks 2 times then do it again 1 hour later (I wanted to be sure that the disk cache was expired) obviously keeping the result cache off
The Results
Run 1 and 3 are querying data directly from Azure Storage you can see that from the local disk cache in Query 1, subsequent Queries use the data cached in the local SSD, notice the cache is temporary, if you suspend your Compute, you may lose it, Although Snowflake tries to give you back the same VM if available.
I plotted the results in PowerBI using the Query history table, The numbers are impressive, I think it is the combination of excellent features working together, great compression, extreme pruning, great Query plan, exact statistics, the whole thing make an extremely efficient engine.
Take away
Database performance is a very complex subject and vary based on the workload, but I wanted to have a simple heuristic, a number that I can reference, I think I have that magic Number 🙂 if your Database can Run TPCH-SF100 around 2 minutes and cost you around 2 $, you can say it is fast.